Qwen3.6-27B-FP8 on AMD ROCm
A reproducible ModelScope DSW study of vLLM ROCm deployment, Qwen MTP speculative decoding, near-8K correctness, FP8 KV cache, and small-concurrency serving behavior.
Strict 1024-token decode: MTP t4 improved median decode throughput from 21.46 tok/s to 54.48 tok/s, about 2.54x.
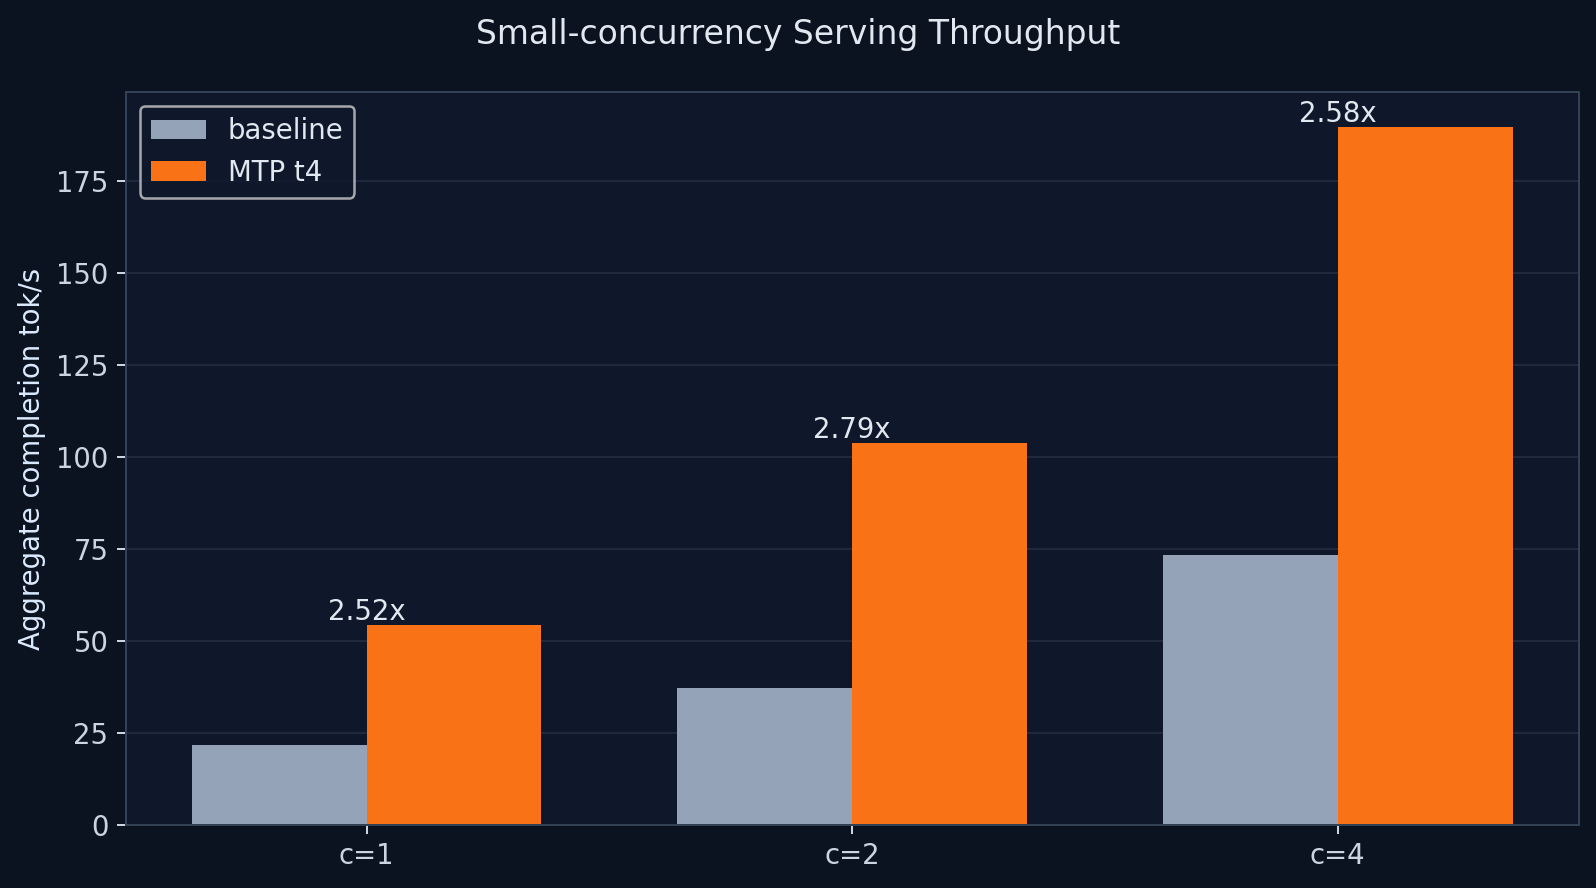
Small-concurrency serving: MTP t4 reached 54.28 / 103.73 / 189.73 tok/s at concurrency 1 / 2 / 4.
Correctness: near-8K needle retrieval passed for MTP t4 and FP8 KV cache paths.
llama.cpp branch: Q4_K_M GGUF passed ROCm llama-cli, llama-server, OpenAI-compatible API, native completion, and restart gates.
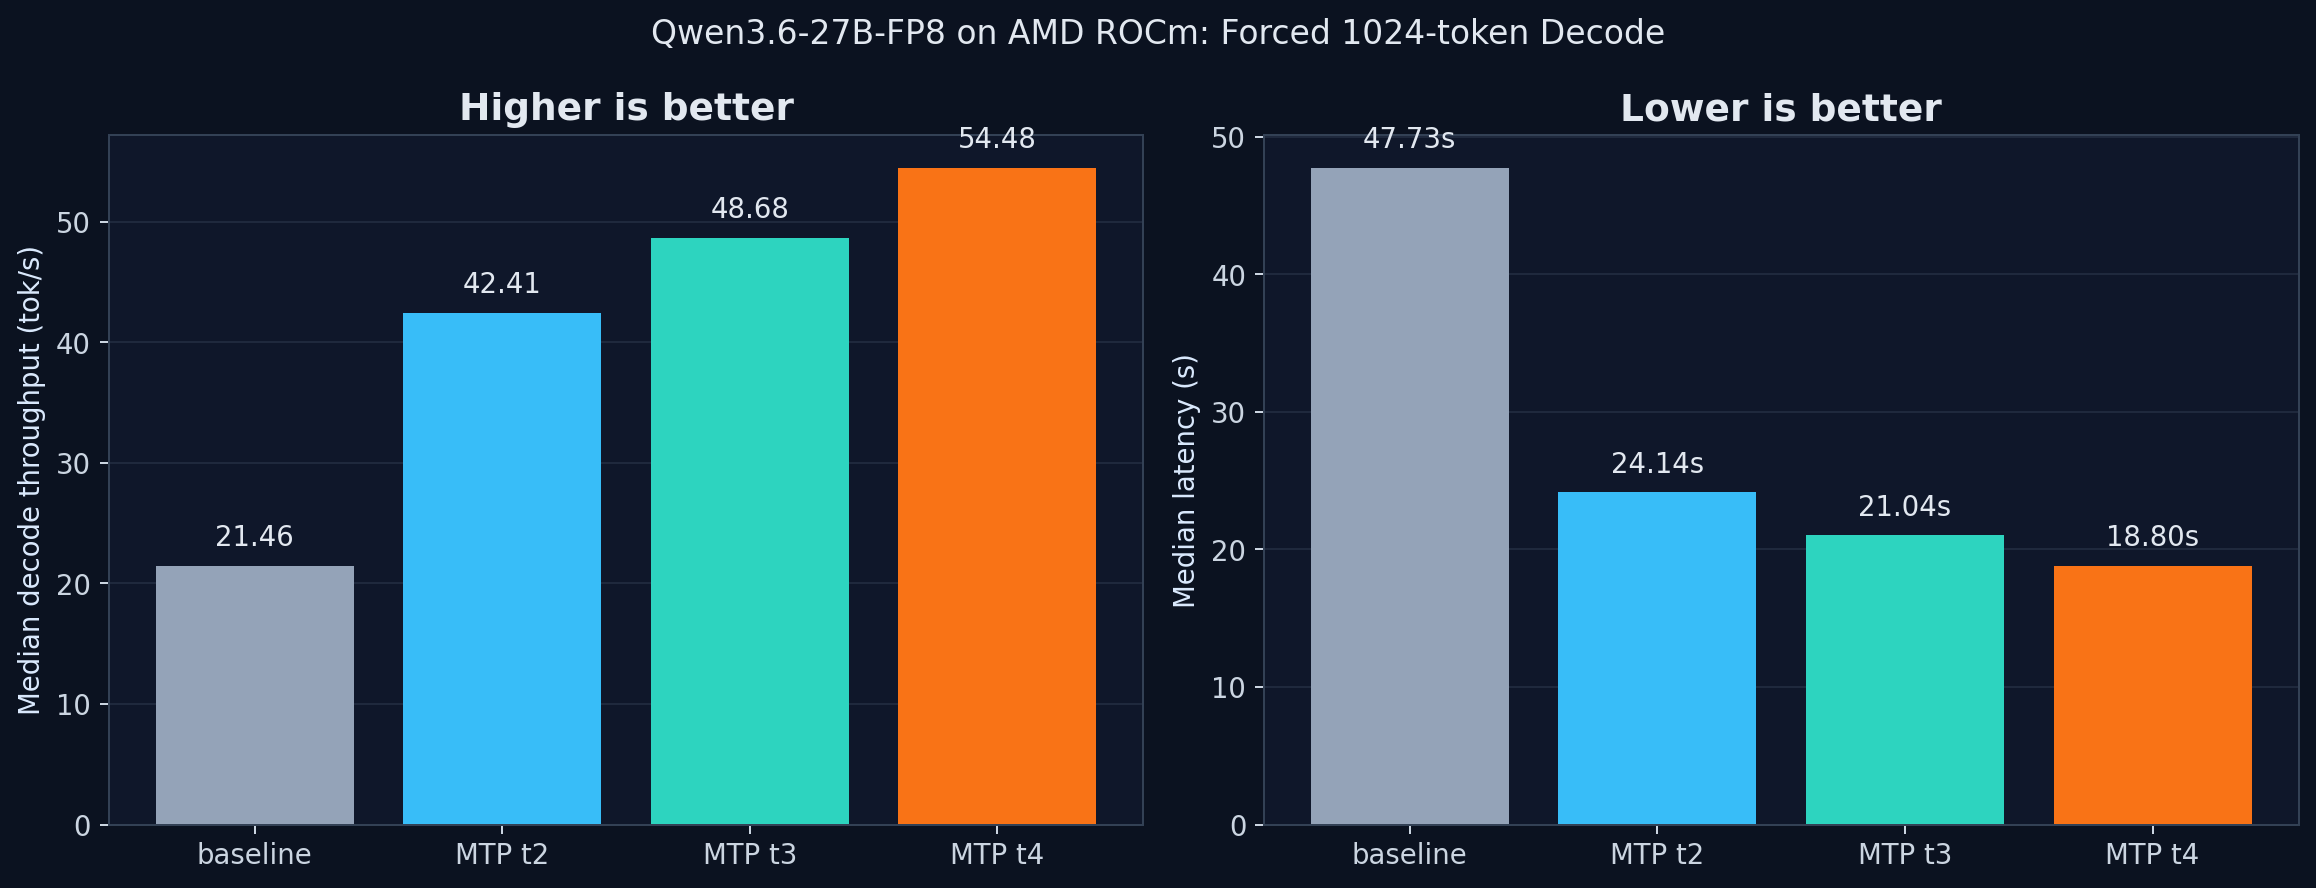
Forced 1024-token Decode
| Configuration | Median latency | Median tok/s | Speedup |
|---|---|---|---|
| baseline | 47.73s | 21.46 | 1.00x |
| MTP t2 | 24.14s | 42.41 | 1.98x |
| MTP t3 | 21.04s | 48.68 | 2.27x |
| MTP t4 | 18.80s | 54.48 | 2.54x |
Small-concurrency Serving
| Concurrency | Baseline tok/s | MTP t4 tok/s | Speedup |
|---|---|---|---|
| 1 | 21.51 | 54.28 | 2.52x |
| 2 | 37.23 | 103.73 | 2.79x |
| 4 | 73.42 | 189.73 | 2.58x |
llama.cpp ROCm Deployment
| Artifact | Runtime | Gate | Result |
|---|---|---|---|
| Q4_K_M GGUF, about 16G | llama-cli ROCm | short generation | RC:0, about 33.4 gen tok/s |
| Q4_K_M GGUF, about 16G | llama-server ROCm | /health, /v1/models, chat, native completion | API_CASES_OK=5/5 |
| Q4_K_M GGUF, about 16G | llama-server ROCm | clean restart and API recheck | RESTART_API_OK=2/2 |
Publication Assets
The public entry points are connected across GitHub, Hugging Face Space, ModelScope Yanxishe, ModelScope Gallery, and Aliyun Developer Community. The repository excludes model weights and keeps scripts, reports, prompts, figures, and publication materials.